The Code Generator That Distrusts Its Own Author
AI agents shipped a Laravel code generator in 26 hours: ten releases, 1,203 tests, a 130-spec corpus. Nobody should trust that sentence. So the same agents built the machinery that assumes the generator is wrong.
On a Wednesday morning in June, AI agents shipped v0.1.0 of openapi-laravel, a code generator that turns an OpenAPI spec into typed Laravel models, validation rules, controllers, and routes. Twenty-six hours and fifteen minutes later they shipped v0.9.0. Ten releases. 1,203 tests, 5,915 assertions. A corpus of 130 real-world OpenAPI specs that every release must survive. GitHub’s API spec alone generates 2,653 PHP files, and all of them lint clean.
You should not trust any of that. I didn’t either, and I’m the author.
The Tool That Didn’t Exist
This project did not start as an AI experiment. It started as a real problem. I worked on a Laravel project and wanted to refactor it from code-driven to spec-driven: the OpenAPI document becomes the source of truth, and the models, validation, and routes follow it.
So I went looking for the tool. The Laravel ecosystem has plenty of packages that go the other way, generating a spec from your code. For the direction I needed, spec in, working Laravel slice out, I found nothing.
I had been here before. A few months earlier my team hit the same kind of gap in the TypeScript world, and I ended up building an OpenAPI toolchain called openapi-zod-ts. Publishing that package and dealing with the first real-user issues taught me the lesson this whole post is about.
Green Tests Prove Nothing
Here is the lesson: telling an AI agent “write an OpenAPI code generator” is easy. The agent will write one. It will write tests for it. The tests will pass. And then you point it at a real project and bugs fall out everywhere.
I lived through that with openapi-zod-ts. The unit tests were green because the agent wrote both the code and the tests, which means the tests encode the code’s own assumptions. They verify the generator does what the generator thinks it should do. They say nothing about whether it does what the spec says.
So when the agents started openapi-laravel, the distrust machinery went in before the features did. The 130-spec corpus came straight over from the sister project. So did the end-to-end harness. The methodology was the part worth porting, more than any line of code.
Three Mechanisms That Cannot Flatter the Author
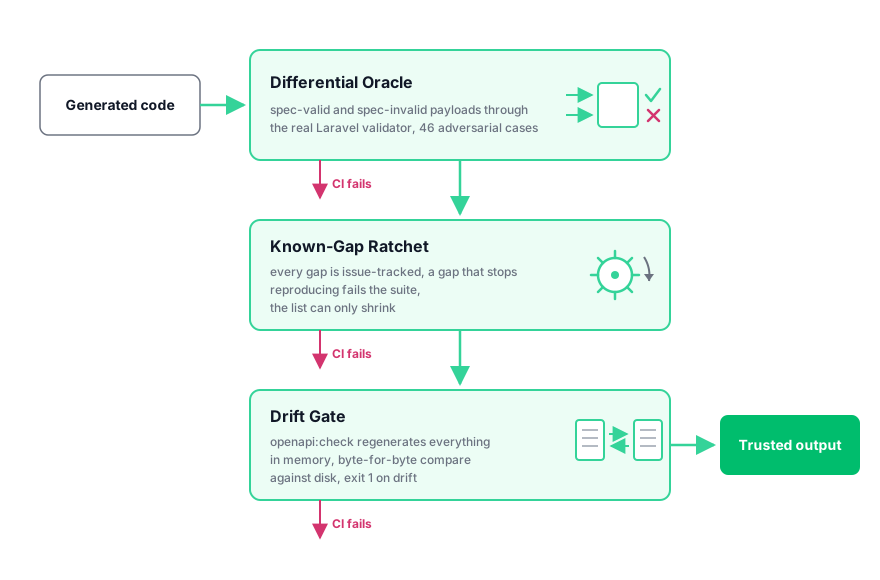
When AI writes the code, trust cannot come from authorship. It has to come from verification machinery that is structurally unable to tell the author what it wants to hear. In openapi-laravel that machinery is three mechanisms stacked on top of each other.
1. The differential oracle. A test harness feeds spec-valid and spec-invalid payloads for every constraint family through the real Laravel validator, running the generated rules(). The catalog behind it holds 46 adversarial constraint cases across six families: strings, numbers, arrays, objects, combinations, unions. The rule is simple: whatever the spec rejects, the generated rules must reject. Any disagreement fails CI. The generator’s opinion of itself never enters the equation, because the oracle compares behavior against the spec, not against the code’s own expectations.
2. The known-gap ratchet. No generator covers everything, and pretending otherwise is how trust dies. Every known gap is an issue-tracked exception in the conformance suite. Right now there are exactly two: additionalProperties: false is not enforced (#30), and undiscriminated object unions are validated as presence-only (#31). The ratchet part: a tracked gap that silently stops reproducing also fails the suite, until someone removes it from the list. Gaps cannot quietly appear, and fixed gaps cannot linger as excuses. The list only shrinks.
3. The drift gate. The package ships an openapi:check command meant for the consumer’s CI. It regenerates the entire file set in memory and compares it byte-for-byte against what’s on disk. Exit 0 means your code matches your spec. Exit 1 fails your build. If someone hand-edits a generated file or the spec moves on without regeneration, CI says so. On the generator’s own side, a golden conformance test pins the output byte-for-byte on every run, which already caught a real regression (#24) before it shipped.
None of these mechanisms care who wrote the code. That is the point.
Compile-Clean Is Not the Bar
Most “AI wrote a code generator” claims stop at compile-clean: the output parses, the linter is happy, ship it. The corpus gates in this project enforce that across 130 specs, and it matters. But it is the lowest bar, not the proof.
The real kicker is the kitchen-sink spec: a deliberately nasty OpenAPI document that exercises nested arrays, unions, formats, nullability, name mapping, every corner at once. The generated code from that spec is not just compiled. It is executed against the contract: requests that the spec allows must hydrate into typed objects, requests the spec forbids must be rejected, responses must round-trip. Compile-clean asks “is this valid PHP?” The kitchen-sink test asks “does this code do what the document promised?” Those are different questions, and the gap between them is where generators silently lie to you.
And the machinery earned its keep before launch. The differential oracle, when it first ran, caught nested-array rules being silently skipped below depth one, format: hostname doing nothing at all, and string-typed constraints being ignored. All fixed by 0.7.0, the release that closed issue #23. No user ever saw those bugs.
Then I Tried to Actually Use It
Now the honest part. Remember the Laravel project this all started for? At 0.6.0 and 0.7.0 I started migrating it. And despite the corpus, the oracle, the golden tests, all of it, I found new bugs instantly.
Real specs written by real teams are weirder than any corpus. Within a day of dogfooding, six fidelity bugs were on the tracker, #48 through #53: type: integer generating PHP floats, PATCH operations registered as Route::post(), a time-format rule that rejected every valid time string, nullable constructor params missing their nullable rule, inconsistent name mapping within a single class, and the same field typed differently in request and response objects.
Six bugs, the day before the launch post was supposed to go out. For a moment that felt like the machinery had failed.
It hadn’t. Here is the twist that made me write this post: while I was hitting those bugs in the field on 0.7.0, the 0.8.0 work was already running in parallel, and its own dogfooding sweep found the same bugs independently. The agents filed them before I got around to reporting what I had seen. The pipeline was already closing them. All six were verified fixed in 0.8.0, released before any launch announcement went out. The machinery wasn’t behind reality. It was catching up to reality on its own, and I just needed a bit more time.
That reframed what the layers actually do. The corpus catches structural failures: code that doesn’t parse, references that don’t resolve. The oracle catches semantic failures: rules that disagree with the spec. But the bugs that survived to my migration were fidelity failures, code that is valid and even spec-plausible but subtly wrong, like a PATCH route that answers to POST. Each layer narrows the class of surviving bugs. None of them eliminates the final layer: a real codebase, used in anger.
The Fact-Check That Bit Me
One more admission, and it happened while writing this very post.
My README claimed the real-world sweep produced 13,378 generated files from nine large public API specs. While fact-checking this article, an agent regenerated every sweep spec from the corpus with default flags, at both the current HEAD and the v0.7.0 tag, and counted roughly 5,900 PHP files. It could not reproduce 13,378 under any default configuration.
NOTE
Every number in this post comes from that fact-check: release timestamps from gh release list, test counts from a live Pest run, file counts from actual regeneration. The 13,378 didn’t survive the check, so it isn’t in this post, and the README gets corrected next.
A post about machinery that refuses to trust the author would be worthless if the marketing copy got a pass. The verified number is smaller and it is the one you get to keep.
Why Not Just Ask an AI to Write It?
Because that question answers itself the moment you try. The agent will write it. It will look done. It will be wrong in ways neither of you can see, and its green test suite will assure you both that everything is fine.
This is not Sonnet 3.5 anymore. The models have moved enormously in a year, and part of why this project exists is that I wanted to know exactly how far: can agents produce production-ready code today, and what does the harness around them have to look like? But the answer was never “the model got good enough, trust it.” The answer is that an agent’s output is only as trustworthy as the adversarial machinery around it. The oracle, the ratchet, the drift gate, the kitchen-sink contract test: that machinery is what I actually built. The generator is what fell out of it.
So when a Laravel developer sees “built by AI agents” in the README and reaches for the close-tab reflex, I don’t ask them to trust the agents. I ask them to read the conformance suite, run openapi:check on their own output, and check the public gap list, which currently holds two items and can only shrink. An AI-built project that publishes what it cannot do is more credible than one that claims everything.
The spec is the source of truth. The code follows it. And nobody gets to take the author’s word for that, least of all the author.